
Google’s Gemini 4 Argon Hallucinates 3x Less Than GPT-6
ALSO: Junior dev jobs fall 20%, AI fools 48% on video calls
Welcome to Guru99 AI Report!
Top Story: If you’re building a career in tech, one number in Stanford’s latest AI Index deserves your attention. We also look at AI that’s learning to run lab equipment, and Gemini’s new knack for admitting when it isn’t sure. Let’s dig in.
🧠 Gemini 4 Argon Hits Paid Plans, Bluffs Far Less
Brief Buzz:
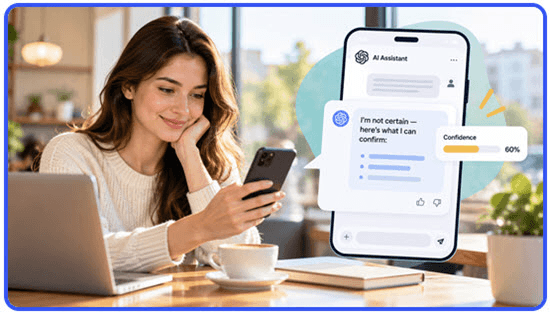
Google has made Gemini 4 Argon available to paying users. It was introduced in the Gemini app for AI Pro and Ultra subscribers on October 13, and developers can use it via the paid API. Its standout trait: it guesses far less when it doesn’t know the answer.
- Independent tester Artificial Analysis measured a 15% hallucination rate (confident wrong answers) versus 51% for GPT-6 Astra.
- Argon’s edge comes from guessing less when unsure — not from knowing more.
- Argon ties GPT-6 Astra at 53 on the Artificial Analysis Intelligence Index, while Claude Opus 5.5 still leads at 58.
- API pricing is $2 / $10 per million tokens (input / output; tokens are word chunks) until November 30, then $4 / $20. Because Argon writes longer outputs, that works out to about 1.2x Astra’s per-task cost.
- Some Googlers say the model struggles with real-world coding, especially front-end design, Bloomberg reported; Google disputes that.
💡 Why Should You Care?
Paying Gemini users should see fewer confidently wrong answers and more “not sure” replies — which means less fact-checking for you. Free users don’t get it yet, and coding claims are worth testing yourself.
🎥 Nearly Half of Testers Thought This AI Was Human

Brief Buzz:
AI startup Tavus has previewed Griffin, a model that holds live video calls as a lifelike person. It sees, hears, talks and reacts in real time — no waiting for its turn to speak. Tavus calls it a “Human Interaction Model.”
- 48% of 54 testers believed Griffin-Lite was human after a one-minute call, up from just 2.4% for Tavus’s earlier system.
- Tavus ran the study itself, and testers were told to expect another person on the call.
- It nods while you talk, handles mid-sentence interruptions and reacts to objects you hold up to the camera.
- Tavus says it led NVIDIA’s VideoFDB test on responses, scoring 3.83 against humans’ 3.92, but lagged on perception.
- Access is limited to trusted testers while Tavus builds disclosure safeguards; no public release date is set.
💡 Why Should You Care?
Lifelike video AI could power patient tutors and far better customer support — but it could also supercharge video-call scams, which makes a clear “this is AI” label essential.
🤖 Stanford’s AI Index: Agents Near Human, Junior Devs Squeezed

Brief Buzz:
Stanford HAI’s 2026 AI Index (released in April) runs 425 pages, and its message is clear: AI isn’t plateauing. Progress is rapid, and 88% of surveyed organizations already use AI. But the data also reveals shaky reliability, patchy safety reporting and early pain for junior tech workers.
- 66.3%: the top AI agent score on OSWorld (369 real computer tasks across Ubuntu, Windows and macOS). CS students hit about 72%, so the gap is now roughly 6 points.
- Roughly 1 in 3: how often AI agents still fail on structured benchmarks. At work, scaled agent use sits in the single digits across most business functions (McKinsey survey cited in the report).
- Nearly 20%: the drop in employment for US software developers aged 22–25 since 2022 (Stanford research using ADP payroll data). Older developers kept growing, and customer service shows the same generational split.
- 26%: the top productivity gain in cited studies, vs. 14–15% in customer support. Judgment-heavy tasks gained the least, and a preprint referenced in the report links heavy AI use to slower skill-building.
- 362: AI incidents logged in the AI Incident Database in 2025, a record (up from 233 in 2024). Safety benchmark reporting remains spotty, and research cited in the report suggests improving safety can cost accuracy.
💡 Why Should You Care?
Agents can now click through real software, but they still fail often and few companies run them at scale. That’s your opening. As junior roles tighten, people who design AI tests, catch agent errors and verify AI output remain in demand. Just keep your own debugging skills sharp instead of handing them off to AI.
🔬 Anthropic’s New Standard Lets AI Run Lab Machines

Brief Buzz:
Anthropic wants AI working at the lab bench. Its new Model Hardware Standard (MHS) gives AI agents a common way to control microscopes, robot arms and other equipment — think MCP, the app connector Anthropic popularized, but for hardware.
- For quantum company QuEra, Claude built a laser-recovery program that succeeded in 695 of 700 test-rig trials, recovering in seconds rather than the 5 to 10 minutes experts need.
- Carnegie Mellon went from disconnected equipment to final results in just 8 hours instead of weeks — including an AI-directed rerun of a bad test.
- A University of Washington PhD student connected his lab, and an AI system now signals when to stop DNA-copying experiments.
- MHS isn’t limited to Claude: it works with any AI model and any device with a programmable interface.
- For now it’s invite-only; Anthropic plans to open-source MHS after the research preview, with no date given.
💡 Why Should You Care?
Lab setups that took weeks could shrink to hours, freeing scientists for real science. But these are early, partner-reported trials, and AI still struggles with real-world physics.
🎙️ ChatGPT Can Now Take Your Meeting Notes

Brief Buzz:
OpenAI has turned ChatGPT into a meeting note-taker. The new Meetings plugin listens to your calls, writes up notes and files a summary with action items into ChatGPT Space, its new shared workspace. It’s in beta on Mac.
- No bot joins the call — it’s listening via your Mac’s mic and system audio, so getting everyone’s consent is on you.
- Summaries are personalized using what ChatGPT already knows about you and your work, per OpenAI’s launch post.
- Audio is deleted once the notes are ready, so you can’t go back and replay the meeting.
- Keep the notes private or share them, then ask ChatGPT to draft a follow-up or update the project plan.
- It’s in beta for Pro and Business users on the macOS desktop app; Enterprise is coming soon.
💡 Why Should You Care?
Standalone note-taking apps now face a real rival in ChatGPT itself. The catch: with no audio to revisit, you can’t verify exact quotes. High-stakes calls will likely still need a recorder.
🛡️ Anthropic Hands Its Most Powerful AI to Cyber Defenders

Brief Buzz:
Anthropic is opening its most capable AI models to more security teams. Its updated Cyber Verification Program lets properly vetted defenders use Claude with far fewer cyber blocks — helping the good guys find and fix software bugs before the bad guys can.
- Three tiers: Defense Access, Red Team Access (authorized hacking) and Specialized Access for critical systems like power grids and telecom networks.
- Every tier includes Mythos 5.1 (Anthropic’s most cyber-capable model), plus Opus 5.5 and Sonnet 5.5.
- Partners identified 129,000+ verified vulnerabilities through Project Glasswing and its earlier invite-only program between April and July, according to a partial Anthropic survey.
- Anthropic’s own scans added 5,500 more; over 33,000 across both sets are rated critical or high severity.
- Top-tier applicants are government-vetted, and every member must let Anthropic retain data to detect misuse.
💡 Why Should You Care?
AI that can find bugs can also exploit them. Anthropic is betting defenders should get the best tools first. The upside is faster patching for hospitals and grids; the risk is that it all comes down to vetting.


Hey! I’m Krishna Rungta
Founder of Guru99.com, Editor-in-chief & Technology Expert
Was this email forwarded to you? Sign up for free here.
