
Scikit-Learn 튜토리얼: 설치 방법 및 Scikit-Learn 예제
 에블린 클라크
⚡ 스마트 요약
Scikit-learn은 오픈 소스입니다. Python 전처리, 분류, 회귀, 클러스터링 및 모델 선택을 하나의 일관된 추정기 인터페이스로 처리하는 라이브러리로, 원시 데이터부터 점수화된 예측에 이르기까지 전체 머신 러닝 워크플로를 간결하고 읽기 쉽고 재현 가능하게 유지합니다.
사이킷런이란?
사이 킷 러닝 오픈 소스입니다 Python 라이브러리 기계 학습이 소프트웨어는 KNN, 그래디언트 부스팅, 랜덤 포레스트, SVM과 같은 잘 알려진 알고리즘을 지원하며, 특정 기반 위에 구축되었습니다. 눔 파이 그리고 SciPy도 있습니다. Scikit-learn은 Kaggle 대회뿐 아니라 유명 IT 기업에서도 널리 사용됩니다. 전처리, 차원 축소, 분류, 회귀, 클러스터링 및 모델 선택 등의 기능을 제공합니다.
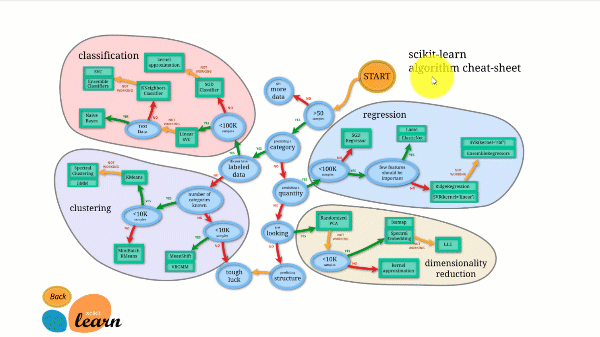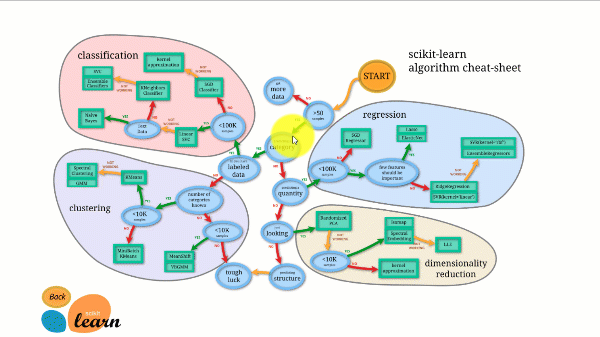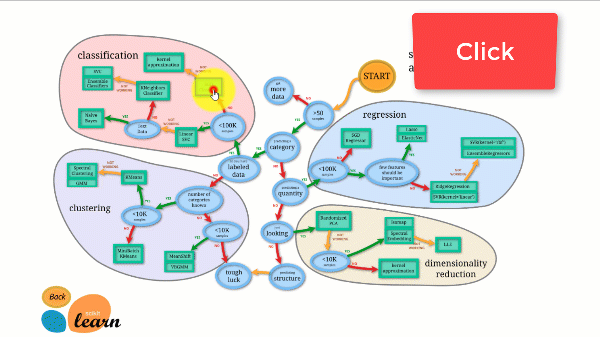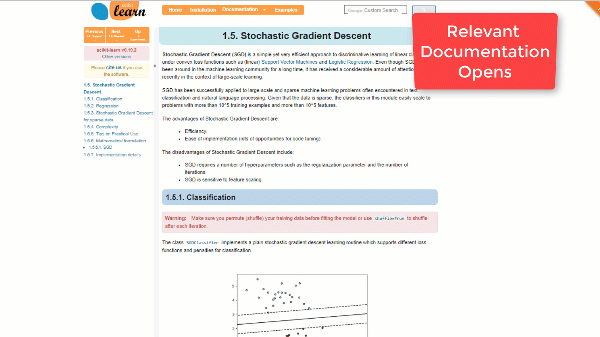
Scikit-learn은 오픈 소스 라이브러리 중에서도 문서화가 가장 잘 되어 있는 편에 속합니다. 심지어 대화형 예측 차트까지 제공합니다. 적합한 견적 담당자 선택하기데이터셋 크기에 따라 시도해 볼 만한 알고리즘 목록을 추려내는 과정을 안내합니다.
아래 그림은 Scikit-learn의 작동 방식을 보여줍니다.
Scikit-learn은 사용하기 어렵지 않고 뛰어난 결과를 제공합니다. 하지만 GPU가 아닌 CPU에서 학습을 진행한다는 점이 특징입니다. n_jobs 인수를 통해 CPU 코어에 작업을 병렬화하여 처리합니다. 따라서 Scikit-learn으로 딥러닝 알고리즘을 실행하는 것은 가능하지만, 특히 이미 다른 방법을 알고 있는 경우에는 최적의 결과를 얻기 어렵습니다. TensorFlow.
Scikit-learn을 다운로드하고 설치하는 방법
이제 이것에서 Python Scikit-learn 튜토리얼에서는 Scikit-learn을 다운로드하고 설치하는 방법을 배웁니다.
옵션 1: AWS
Scikit-learn은 AWS 환경에서도 사용할 수 있습니다. Scikit-learn이 사전 설치된 Docker 이미지를 사용하면 설정 작업을 완전히 생략할 수 있습니다.
개발자 버전을 설치하려면 아래 명령어를 실행하세요. Jupyter:
import sys
!{sys.executable} -m pip install git+git://github.com/scikit-learn/scikit-learn.git
옵션 2: 맥 또는 Windows 아나콘다를 사용하여
Anaconda 설치에 대한 자세한 내용은 다음을 참조하십시오. TensorFlow 다운로드 및 설치 방법.
이 가이드가 작성될 당시 scikit-learn 개발팀은 최신 릴리스에 있던 문제를 수정한 개발 버전을 출시했으므로 아래 단계에서는 해당 개발 버전을 사용합니다. 오늘날 새로 설치한 컴퓨터에는 최신 안정 버전에 여기에 사용된 모든 트랜스포머가 이미 포함되어 있습니다. pip install -U scikit-learn 충분하다.
Conda 환경에서 scikit-learn을 설치하는 방법
conda 환경을 사용하여 scikit-learn을 설치한 경우 아래 단계를 따라 버전 0.20으로 업데이트하십시오.
1단계) TensorFlow 환경을 활성화합니다.
source activate hello-tf
2단계) conda 명령어를 사용하여 scikit-learn을 제거합니다.
conda remove scikit-learn
3단계) 개발자 버전을 설치합니다.
scikit-learn 개발자 버전과 필요한 라이브러리를 설치하세요.
conda install -c anaconda git
pip install Cython
pip install h5py
pip install git+git://github.com/scikit-learn/scikit-learn.git
알림: Windows 사용자는 필요합니다 Microsoft 시각 C++ 14. 당신은 그것을 얻을 수 있습니다. 여기에서 확인하세요.
기계 학습을 사용한 Scikit-Learn 예
이 Scikit 튜토리얼은 두 부분으로 나누어져 있습니다:
- scikit-learn을 사용한 머신러닝
- LIME으로 모델을 신뢰하는 방법
첫 번째 부분에서는 파이프라인 구축, 모델 생성 및 하이퍼파라미터 튜닝 방법을 자세히 설명하고, 두 번째 부분에서는 모델 해석을 다룹니다.
1단계) 데이터 가져오기
이번 Scikit-learn 튜토리얼에서는 성인 인구 조사 데이터셋을 사용하게 됩니다.
아래 코드는 UCI 머신러닝 저장소에서 파일을 직접 읽어오므로 수동으로 다운로드할 필요가 없습니다. 기술 통계에 관심이 있다면 Dive 및 Overview 도구를 살펴보는 것이 좋습니다. 자세한 내용은 다음을 참조하세요. 이 튜토리얼 Dive 및 Overview에 대해 자세히 알아보려면 다음을 참조하세요.
pandas를 사용하여 데이터셋을 가져옵니다. 연속형 변수는 부동소수점 형식으로 변환해야 합니다.
이 데이터 세트에는 CATE_FEATURES에 나열된 8개의 범주형 변수가 포함되어 있습니다.
- 작업반
- 교육
- 결혼의
- 직업
- 관계
- 경주
- 섹스
- 원주민_국가
또한 CONTI_FEATURES에 나열된 6개의 연속 변수도 포함됩니다.
- 나이
- fnlwgt
- education_num
- 자본 이득
- 자본 손실
- 시간_주
여기서는 어떤 열이 사용되는지 더 명확하게 파악할 수 있도록 목록을 수동으로 작성했습니다. 범주형 또는 연속형 열 목록을 더 빠르게 만드는 방법은 다음과 같습니다.
## List Categorical
CATE_FEATURES = df_train.iloc[:,:-1].select_dtypes('object').columns
print(CATE_FEATURES)

## List continuous
CONTI_FEATURES =  df_train._get_numeric_data()
print(CONTI_FEATURES)
데이터를 가져오는 코드는 다음과 같습니다.
# Import dataset
import pandas as pd

## Define path data
COLUMNS = ['age','workclass', 'fnlwgt', 'education', 'education_num', 'marital',
           'occupation', 'relationship', 'race', 'sex', 'capital_gain', 'capital_loss',
           'hours_week', 'native_country', 'label']
### Define continuous list
CONTI_FEATURES  = ['age', 'fnlwgt','capital_gain', 'education_num', 'capital_loss', 'hours_week']
### Define categorical list
CATE_FEATURES = ['workclass', 'education', 'marital', 'occupation', 'relationship', 'race', 'sex', 'native_country']

## Prepare the data
features = ['age','workclass', 'fnlwgt', 'education', 'education_num', 'marital',
           'occupation', 'relationship', 'race', 'sex', 'capital_gain', 'capital_loss',
           'hours_week', 'native_country']

PATH = "https://archive.ics.uci.edu/ml/machine-learning-databases/adult/adult.data"

df_train = pd.read_csv(PATH, skipinitialspace=True, names = COLUMNS, index_col=False)
df_train[CONTI_FEATURES] =df_train[CONTI_FEATURES].astype('float64')
df_train.describe()
프레임에서 describe()를 호출하면 6개의 연속형 열에 대한 요약 통계가 반환됩니다.
| 나이 | fnlwgt | education_num | 자본 이득 | 자본 손실 | 시간_주 | |
|---|---|---|---|---|---|---|
| 계산 | 32561.000000 | 3.256100e + 04 | 32561.000000 | 32561.000000 | 32561.000000 | 32561.000000 |
| 평균 | 38.581647 | 1.897784e + 05 | 10.080679 | 1077.648844 | 87.303830 | 40.437456 |
| 표준 | 13.640433 | 1.055500e + 05 | 2.572720 | 7385.292085 | 402.960219 | 12.347429 |
| 분 | 17.000000 | 1.228500e + 04 | 1.000000 | 0.000000 | 0.000000 | 1.000000 |
| 25% | 28.000000 | 1.178270e + 05 | 9.000000 | 0.000000 | 0.000000 | 40.000000 |
| 50% | 37.000000 | 1.783560e + 05 | 10.000000 | 0.000000 | 0.000000 | 40.000000 |
| 75% | 48.000000 | 2.370510e + 05 | 12.000000 | 0.000000 | 0.000000 | 45.000000 |
| 최대 | 90.000000 | 1.484705e + 06 | 16.000000 | 99999.000000 | 4356.000000 | 99.000000 |
native_country 특성의 고유값 개수를 확인할 수 있습니다. 네덜란드(홀란드) 출신 가구는 단 한 가구뿐입니다. 해당 가구는 아무런 정보도 제공하지 않으므로 학습 과정에서 오류가 발생합니다.
df_train.native_country.value_counts()
United-States                 29170
Mexico                          643
?                               583
Philippines                     198
Germany                         137
Canada                          121
Puerto-Rico                     114
El-Salvador                     106
India                           100
Cuba                             95
England                          90
Jamaica                          81
South                            80
China                            75
Italy                            73
Dominican-Republic               70
Vietnam                          67
Guatemala                        64
Japan                            62
Poland                           60
Columbia                         59
Taiwan                           51
Haiti                            44
Iran                             43
Portugal                         37
Nicaragua                        34
Peru                             31
France                           29
Greece                           29
Ecuador                          28
Ireland                          24
Hong                             20
Cambodia                         19
Trinadad&Tobago                  19
Thailand                         18
Laos                             18
Yugoslavia                       16
Outlying-US(Guam-USVI-etc)       14
Honduras                         13
Hungary                          13
Scotland                         12
Holand-Netherlands                1
Name: native_country, dtype: int64
이처럼 정보가 부족한 행을 데이터 세트에서 제외할 수 있습니다.
## Drop Netherland, because only one row
df_train = df_train[df_train.native_country != "Holand-Netherlands"]
다음으로 연속 기능의 위치를 목록에 저장합니다. 파이프라인을 빌드하려면 다음 단계에서 필요합니다.
아래 코드는 CONTI_FEATURES 테이블의 모든 열 이름을 순회하면서 각 열의 위치(즉, 열 번호)를 읽어 conti_features라는 리스트에 추가합니다.
## Get the column index of the categorical features
conti_features = []
for i in CONTI_FEATURES:
    position = df_train.columns.get_loc(i)
    conti_features.append(position)
print(conti_features)
[0, 2, 10, 4, 11, 12]
다음 블록은 범주형 변수에 대해서도 동일한 작업을 수행합니다.
## Get the column index of the categorical features
categorical_features = []
for i in CATE_FEATURES:
    position = df_train.columns.get_loc(i)
    categorical_features.append(position)
print(categorical_features)
[1, 3, 5, 6, 7, 8, 9, 13]
이제 데이터셋 자체를 살펴보겠습니다. 각 범주형 변수는 문자열이며, 모델에는 문자열 값을 입력할 수 없으므로 더미 변수를 사용하여 데이터셋을 변환해야 합니다.
df_train.head(5)
실제로 각 피처의 각 그룹마다 하나의 열이 필요합니다. 먼저 아래 코드를 실행하여 필요한 총 열 수를 계산하세요.
print(df_train[CATE_FEATURES].nunique(),
      'There are',sum(df_train[CATE_FEATURES].nunique()), 'groups in the whole dataset')
workclass          9
education         16
marital            7
occupation        15
relationship       6
race               5
sex                2
native_country    41
dtype: int64 There are 101 groups in the whole dataset
위에서 보는 것처럼 전체 데이터셋에는 101개의 그룹이 있습니다. 직종(workclass) 특성만 해도 9개의 그룹으로 구성되어 있습니다. 아래 코드를 사용하면 그룹 이름을 나열할 수 있으며, unique() 함수는 각 범주형 특성의 고유값을 반환합니다.
for i in CATE_FEATURES:
    print(df_train[i].unique())
['State-gov' 'Self-emp-not-inc' 'Private' 'Federal-gov' 'Local-gov' '?'
 'Self-emp-inc' 'Without-pay' 'Never-worked']
['Bachelors' 'HS-grad' '11th' 'Masters' '9th' 'Some-college' 'Assoc-acdm'
 'Assoc-voc' '7th-8th' 'Doctorate' 'Prof-school' '5th-6th' '10th'
 '1st-4th' 'Preschool' '12th']
['Never-married' 'Married-civ-spouse' 'Divorced' 'Married-spouse-absent'
 'Separated' 'Married-AF-spouse' 'Widowed']
['Adm-clerical' 'Exec-managerial' 'Handlers-cleaners' 'Prof-specialty'
 'Other-service' 'Sales' 'Craft-repair' 'Transport-moving'
 'Farming-fishing' 'Machine-op-inspct' 'Tech-support' '?'
 'Protective-serv' 'Armed-Forces' 'Priv-house-serv']
['Not-in-family' 'Husband' 'Wife' 'Own-child' 'Unmarried' 'Other-relative']
['White' 'Black' 'Asian-Pac-Islander' 'Amer-Indian-Eskimo' 'Other']
['Male' 'Female']
['United-States' 'Cuba' 'Jamaica' 'India' '?' 'Mexico' 'South'
 'Puerto-Rico' 'Honduras' 'England' 'Canada' 'Germany' 'Iran'
 'Philippines' 'Italy' 'Poland' 'Columbia' 'Cambodia' 'Thailand' 'Ecuador'
 'Laos' 'Taiwan' 'Haiti' 'Portugal' 'Dominican-Republic' 'El-Salvador'
 'France' 'Guatemala' 'China' 'Japan' 'Yugoslavia' 'Peru'
 'Outlying-US(Guam-USVI-etc)' 'Scotland' 'Trinadad&Tobago' 'Greece'
 'Nicaragua' 'Vietnam' 'Hong' 'Ireland' 'Hungary']
따라서 훈련 데이터 세트는 원핫 인코딩 그룹과 6개의 연속형 특징을 포함하여 총 101 + 6개의 열을 포함하게 됩니다.
Scikit-learn은 다음 두 단계를 통해 변환을 처리할 수 있습니다.
- 문자열을 ID로 변환합니다. State-gov는 ID 1이 되고, Self-emp-not-inc는 ID 2가 되는 식입니다. LabelEncoder가 이 작업을 자동으로 수행해 줍니다.
- 각 ID를 새로운 열로 변환합니다. 데이터셋에는 101개의 그룹 ID가 있으므로 모든 범주형 특징 그룹을 나타내는 101개의 열이 생성됩니다. Scikit-learn은 이 작업을 위해 OneHotEncoder를 제공합니다.
2단계) 열차/테스트 세트 생성
데이터셋이 준비되었으니 80/20 비율로 분할합니다. 80%는 훈련 세트로, 20%는 테스트 세트로 사용합니다.
`train_test_split` 함수를 사용할 수 있습니다. 첫 번째 인수는 특징 데이터프레임이고 두 번째 인수는 레이블입니다. 테스트 세트의 크기는 `test_size`로 설정합니다.
from sklearn.model_selection import train_test_split
X_train, X_test, y_train, y_test = train_test_split(df_train[features],
                                                    df_train.label,
                                                    test_size = 0.2,
                                                    random_state=0)
X_train.head(5)
print(X_train.shape, X_test.shape)
(26048, 14) (6512, 14)
3단계) 파이프라인 구축
파이프라인을 사용하면 모델에 일관된 데이터를 더 쉽게 공급할 수 있습니다. 핵심 아이디어는 모든 연산을 순서대로 수행하는 단일 객체를 통해 원시 데이터를 전달하는 것입니다.
이 데이터셋에서는 연속형 변수를 표준화하고 범주형 변수를 변환해야 합니다. 파이프라인 내에서 모든 작업을 수행할 수 있습니다. 예를 들어 결측값은 평균이나 중앙값으로 대체할 수 있고, 새로운 변수를 생성할 수도 있습니다.
두 프로세스를 직접 코드로 작성하거나 파이프라인을 구축하는 두 가지 방법이 있습니다. 직접 코드를 작성하면 테스트 데이터가 적합된 통계에 유입되어 시간이 지남에 따라 일관성이 떨어질 수 있으므로 파이프라인을 사용하는 것이 더 나은 선택입니다.
from sklearn.preprocessing import StandardScaler, OneHotEncoder, LabelEncoder
from sklearn.compose import ColumnTransformer, make_column_transformer
from sklearn.pipeline import make_pipeline
from sklearn.linear_model import LogisticRegression
파이프라인은 로지스틱 분류기에 입력하기 전에 두 가지 작업을 수행합니다.
- 변수를 표준화합니다: StandardScaler()
- 범주형 기능 변환: OneHotEncoder(sparse=False)
make_column_transformer 함수를 사용하여 두 단계를 모두 수행합니다. 이 가이드가 작성될 당시에는 해당 함수가 scikit-learn의 정식 버전(0.19)에 포함되어 있지 않았기 때문에 개발자 빌드를 사용했습니다. 이 함수는 0.20 버전 이후의 모든 안정 버전에 포함되어 있습니다.
make_column_transformer는 간단합니다. 변환할 열과 적용할 변환을 선언하면 됩니다. 연속형 기능을 표준화하려면 다음을 전달합니다.
- conti_features, make_column_transformer 내부의 StandardScaler()
- conti_features: 연속형 열 목록
- StandardScaler: 해당 열들을 표준화합니다.
make_column_transformer 함수 내부의 OneHotEncoder 객체는 레이블을 자동으로 인코딩합니다.
preprocess = make_column_transformer(
    (conti_features, StandardScaler()),
    ### Need to be numeric not string to specify columns name
    (categorical_features, OneHotEncoder(sparse=False))
)
버전 참고: 위 블록의 두 인수가 이동했습니다. 현재 릴리스에서는 변환기가 먼저 오고 열이 그 다음에 오는 것을 예상합니다. 부족한 이름이 바뀌다 희소 출력 scikit-learn 1.2 버전에 있었고 1.4 버전에서 제거되었으므로 최신 코드는 다음과 같습니다. 원핫인코더(sparse_output=False).
`fit_transform` 함수를 사용하여 파이프라인이 제대로 작동하는지 테스트할 수 있습니다. 출력 결과는 `26048, 107` 형태여야 합니다.
preprocess.fit_transform(X_train).shape
(26048, 107)
데이터 변환기가 준비되었습니다. make_pipeline 명령으로 파이프라인을 생성하고, 데이터 변환이 완료되면 로지스틱 회귀 분석에 데이터를 입력합니다.
model = make_pipeline(
    preprocess,
    LogisticRegression())
scikit-learn을 사용하여 모델을 학습시키는 것은 매우 간단합니다. 파이프라인에서 fit 메서드를 호출하기만 하면 됩니다. score 메서드를 사용하면 정확도를 출력할 수 있습니다.
model.fit(X_train, y_train)
print("logistic regression score: %f" % model.score(X_test, y_test))
logistic regression score: 0.850891
마지막으로 predict_proba 함수를 사용하여 각 클래스의 확률을 예측할 수 있습니다. 두 확률의 합은 1이라는 점에 유의하세요.
model.predict_proba(X_test)
array([[0.83576663, 0.16423337],
       [0.94582765, 0.05417235],
       [0.64760587, 0.35239413],
       ...,
       [0.99639252, 0.00360748],
       [0.02072181, 0.97927819],
       [0.56781353, 0.43218647]])
4단계) 그리드 검색에서 파이프라인 사용
모델의 구조를 결정하는 값인 하이퍼파라미터를 조정하는 것은 지루하고 힘든 작업일 수 있습니다.
모델을 평가하는 한 가지 방법은 훈련 데이터셋의 크기를 변경하고 성능을 측정하는 것입니다. 이 과정을 10회 반복하여 점수 분포를 살펴보는 것이죠. 하지만 이는 상당한 수작업이 필요합니다.
대신 scikit-learn은 매개변수 조정 및 교차 검증을 수행하는 함수를 제공합니다.
교차 검증
교차 검증이란 학습 과정에서 학습 데이터셋을 n번 폴드로 분할하고, 각 폴드를 n번 평가하는 것을 의미합니다. 예를 들어, cv 값을 10으로 설정하면 모델을 10번 학습하고 평가합니다. 각 단계에서 분류기는 무작위로 선택된 9개의 폴드를 사용하여 학습하고, 나머지 1개의 폴드를 평가에 사용합니다.
그리드 검색
모든 분류기에는 조정할 수 있는 하이퍼파라미터가 있습니다. 값을 하나씩 시도해 보거나, 파라미터 그리드를 설정할 수 있습니다. scikit-learn 문서에는 로지스틱 분류기가 허용하는 모든 파라미터가 나열되어 있습니다. 학습 속도를 유지하기 위해 이 예제에서는 정규화를 제어하는 C 파라미터만 조정합니다. C 파라미터는 양수여야 하며, 값이 작을수록 정규화에 더 큰 가중치가 부여됩니다.
GridSearchCV 객체를 사용하면 튜닝할 하이퍼파라미터 목록을 담은 딕셔너리를 받을 수 있습니다. 각 하이퍼파라미터와 시도해 볼 값을 나열하세요. C를 튜닝하려면 다음과 같이 작성합니다.
- 'logisticregression__C': [0.001, 0.01, 0.1, 1.0] — 매개변수 이름 앞에는 소문자로 된 분류기 이름과 두 개의 밑줄이 붙습니다.
이 모델은 0.001, 0.01, 0.1, 1의 네 가지 값을 시도합니다. 10겹 교차 검증(cv=10)으로 학습됩니다.
from sklearn.model_selection import GridSearchCV
# Construct the parameter grid
param_grid = {
    'logisticregression__C': [0.001, 0.01,0.1, 1.0],
    }
이제 grid와 cv 매개변수를 사용하여 GridSearchCV로 모델을 학습시킬 수 있습니다.
# Train the model
grid_clf = GridSearchCV(model,
                        param_grid,
                        cv=10,
                        iid=False)
grid_clf.fit(X_train, y_train)
출력:
GridSearchCV(cv=10, error_score='raise-deprecating',
       estimator=Pipeline(memory=None,
     steps=[('columntransformer', ColumnTransformer(n_jobs=1, remainder='drop', transformer_weights=None,
         transformers=[('standardscaler', StandardScaler(copy=True, with_mean=True, with_std=True), [0, 2, 10, 4, 11, 12]), ('onehotencoder', OneHotEncoder(categorical_features=None, categories=None,...ty='l2', random_state=None, solver='liblinear', tol=0.0001,
          verbose=0, warm_start=False))]),
       fit_params=None, iid=False, n_jobs=1,
       param_grid={'logisticregression__C': [0.001, 0.01, 0.1, 1.0]},
       pre_dispatch='2*n_jobs', refit=True, return_train_score='warn',
       scoring=None, verbose=0)
버전 참고: 전에, 이드 이 출력에 표시된 인수는 scikit-learn 0.22에서 더 이상 사용되지 않도록 권장되었고 0.24에서 제거되었으므로 현재 릴리스에서는 GridSearchCV 호출에서 해당 인수를 삭제해야 합니다.
최적의 매개변수에 접근하려면 best_params_를 사용합니다.
grid_clf.best_params_
출력:
{'logisticregression__C': 1.0}
서로 다른 네 가지 정규화 값으로 모델을 학습시킨 결과, 최적의 매개변수 값은 다음과 같습니다.
print("best logistic regression from grid search: %f" % grid_clf.best_estimator_.score(X_test, y_test))
그리드 검색에서 가장 좋은 로지스틱 회귀: 0.850891
예측 확률에 액세스하려면 다음을 수행하세요.
grid_clf.best_estimator_.predict_proba(X_test)
array([[0.83576677, 0.16423323],
       [0.9458291 , 0.0541709 ],
       [0.64760416, 0.35239584],
       ...,
       [0.99639224, 0.00360776],
       [0.02072033, 0.97927967],
       [0.56782222, 0.43217778]])
scikit-learn을 사용한 XGBoost 모델
이제 시중에서 가장 강력한 분류기 중 하나를 사용해 보세요. XGBoost는 랜덤 포레스트를 그래디언트 부스팅 기법으로 개선한 모델입니다. 이론적 배경은 이 글의 범위를 벗어나므로 자세히 다루지는 않겠습니다. Python Scikit-learn 튜토리얼을 참고하세요. 하지만 XGBoost는 수많은 Kaggle 대회에서 우승을 차지했다는 점을 기억해 두세요. 평균 크기의 데이터셋에서는 딥러닝 알고리즘만큼, 혹은 그 이상의 성능을 보여줄 수 있습니다.
이 분류기는 매개변수가 많아 학습시키기가 어렵습니다. 물론 GridSearchCV를 사용하여 매개변수를 선택할 수 있습니다.
이 경우 RandomizedSearchCV가 더 나은 선택입니다. GridSearchCV는 그리드가 커질수록 탐색 공간이 매개변수가 추가될 때마다 증가하기 때문에 속도가 느려집니다. RandomizedSearchCV는 대신 각 하이퍼파라미터의 값을 매 반복마다 무작위로 샘플링하므로 1,000번의 반복에서 1,000가지 조합을 평가합니다. 그 외의 작동 방식은 GridSearchCV와 거의 동일합니다.
xgboost 라이브러리를 임포트해야 합니다. 라이브러리가 설치되어 있지 않으면 `pip3 install xgboost` 명령을 실행하거나, `xgboost` 실행 파일 내에서 설치하십시오. Jupyter 노트북 내용:
use import sys
!{sys.executable} -m pip install xgboost
다음으로 분류기와 두 개의 검색 도우미를 가져옵니다.
import xgboost
from sklearn.model_selection import RandomizedSearchCV
from sklearn.model_selection import StratifiedKFold
이 Scikit의 다음 단계 Python 이 튜토리얼의 목적은 조정할 매개변수를 지정하는 것입니다. XGBoost 공식 문서에 모든 매개변수가 나열되어 있습니다. 이 튜토리얼에서는 그 매개변수를 구체적으로 설명합니다. Python Sklearn 튜토리얼에서는 XGBoost 학습에 오랜 시간이 걸리고 그리드 포인트가 추가될 때마다 대기 시간이 늘어나기 때문에 각각 두 개의 값으로 구성된 두 개의 하이퍼파라미터만 선택합니다.
params = {
        'xgbclassifier__gamma': [0.5, 1],
        'xgbclassifier__max_depth': [3, 4]
        }
다음으로 XGBoost 분류기와 600개의 추정기를 사용하여 새로운 파이프라인을 구성합니다. n_estimators는 조정 가능한 값이며, 너무 높은 값은 과적합을 초래할 수 있습니다. 다른 값을 시도해 볼 수 있지만, 이 과정은 몇 시간씩 걸릴 수 있다는 점에 유의하십시오. 다른 모든 매개변수는 기본값을 유지합니다.
model_xgb = make_pipeline(
    preprocess,
    xgboost.XGBClassifier(
                          n_estimators=600,
                          objective='binary:logistic',
                          silent=True,
                          nthread=1)
)
계층화된 K-폴드 교차 검증기를 사용하면 교차 검증 성능을 향상시킬 수 있습니다. 여기서는 계산 속도를 높이기 위해 3개의 폴드만 사용했지만, 이로 인해 품질이 다소 저하될 수 있습니다. 더 나은 결과를 얻으려면 실제 사용 환경에서 폴드 수를 5개 또는 10개로 늘리십시오. 모델은 4번의 반복 학습을 거칩니다.
skf = StratifiedKFold(n_splits=3,
                      shuffle = True,
                      random_state = 1001)

random_search = RandomizedSearchCV(model_xgb,
                                   param_distributions=params,
                                   n_iter=4,
                                   scoring='accuracy',
                                   n_jobs=4,
                                   cv=skf.split(X_train, y_train),
                                   verbose=3,
                                   random_state=1001)
무작위 검색 기능이 준비되었으므로 모델을 학습시킬 수 있습니다.
#grid_xgb = GridSearchCV(model_xgb, params, cv=10, iid=False)
random_search.fit(X_train, y_train)
Fitting 3 folds for each of 4 candidates, totalling 12 fits
[CV] xgbclassifier__max_depth=3, xgbclassifier__gamma=0.5 ............
[CV] xgbclassifier__max_depth=3, xgbclassifier__gamma=0.5 ............
[CV] xgbclassifier__max_depth=3, xgbclassifier__gamma=0.5 ............
[CV] xgbclassifier__max_depth=4, xgbclassifier__gamma=0.5 ............
[CV]  xgbclassifier__max_depth=3, xgbclassifier__gamma=0.5, score=0.8759645283888057, total= 1.0min
[CV] xgbclassifier__max_depth=4, xgbclassifier__gamma=0.5 ............
[CV]  xgbclassifier__max_depth=3, xgbclassifier__gamma=0.5, score=0.8729701715996775, total= 1.0min
[CV]  xgbclassifier__max_depth=3, xgbclassifier__gamma=0.5, score=0.8706519235199263, total= 1.0min
[CV] xgbclassifier__max_depth=4, xgbclassifier__gamma=0.5 ............
[CV] xgbclassifier__max_depth=3, xgbclassifier__gamma=1 ..............
[CV]  xgbclassifier__max_depth=4, xgbclassifier__gamma=0.5, score=0.8735460094437406, total= 1.3min
[CV] xgbclassifier__max_depth=3, xgbclassifier__gamma=1 ..............
[CV]  xgbclassifier__max_depth=3, xgbclassifier__gamma=1, score=0.8722791661868018, total=  57.7s
[CV] xgbclassifier__max_depth=3, xgbclassifier__gamma=1 ..............
[CV]  xgbclassifier__max_depth=3, xgbclassifier__gamma=1, score=0.8753886905447426, total= 1.0min
[CV] xgbclassifier__max_depth=4, xgbclassifier__gamma=1 ..............
[CV]  xgbclassifier__max_depth=4, xgbclassifier__gamma=0.5, score=0.8697304768486523, total= 1.3min
[CV] xgbclassifier__max_depth=4, xgbclassifier__gamma=1 ..............
[CV]  xgbclassifier__max_depth=4, xgbclassifier__gamma=0.5, score=0.8740066797189912, total= 1.4min
[CV] xgbclassifier__max_depth=4, xgbclassifier__gamma=1 ..............
[CV]  xgbclassifier__max_depth=3, xgbclassifier__gamma=1, score=0.8707671043538355, total= 1.0min
[CV]  xgbclassifier__max_depth=4, xgbclassifier__gamma=1, score=0.8729701715996775, total= 1.2min
[Parallel(n_jobs=4)]: Done  10 out of  12 | elapsed:  3.6min remaining:   43.5s
[CV]  xgbclassifier__max_depth=4, xgbclassifier__gamma=1, score=0.8736611770125533, total= 1.2min
[CV]  xgbclassifier__max_depth=4, xgbclassifier__gamma=1, score=0.8692697535130154, total= 1.2min
[Parallel(n_jobs=4)]: Done  12 out of  12 | elapsed:  3.6min finished
/Users/Thomas/anaconda3/envs/hello-tf/lib/python3.6/site-packages/sklearn/model_selection/_search.py:737: DeprecationWarning: The default of the `iid` parameter will change from True to False in version 0.22 and will be removed in 0.24. This will change numeric results when test-set sizes are unequal. DeprecationWarning)
RandomizedSearchCV(cv=<generator object _BaseKFold.split at 0x1101eb830>,
          error_score='raise-deprecating',
          estimator=Pipeline(memory=None,
     steps=[('columntransformer', ColumnTransformer(n_jobs=1, remainder='drop', transformer_weights=None,
         transformers=[('standardscaler', StandardScaler(copy=True, with_mean=True, with_std=True), [0, 2, 10, 4, 11, 12]), ('onehotencoder', OneHotEncoder(categorical_features=None, categories=None,...
       reg_alpha=0, reg_lambda=1, scale_pos_weight=1, seed=None,
       silent=True, subsample=1))]),
          fit_params=None, iid='warn', n_iter=4, n_jobs=4,
          param_distributions={'xgbclassifier__gamma': [0.5, 1], 'xgbclassifier__max_depth': [3, 4]},
          pre_dispatch='2*n_jobs', random_state=1001, refit=True,
          return_train_score='warn', scoring='accuracy', verbose=3)
보시다시피, XGBoost는 기존 로지스틱 회귀 분석보다 더 나은 성능을 보입니다.
print("최고의 parameter", random_search.best_params_)
print("best logistic regression from grid search: %f" % random_search.best_estimator_.score(X_test, y_test))
최고의 parameter {'xgbclassifier__max_depth': 3, 'xgbclassifier__gamma': 0.5}
best logistic regression from grid search: 0.873157
random_search.best_estimator_.predict(X_test)
array(['<=50K', '<=50K', '<=50K', ..., '<=50K', '>50K', '<=50K'], dtype=object)
scikit-learn에서 MLPClassifier를 사용하여 DNN 생성
마지막으로, scikit-learn 자체를 사용하여 신경망을 학습시킬 수 있습니다. 방법은 다른 분류기와 동일하며, 추정기는 MLPClassifier입니다.
from sklearn.neural_network import MLPClassifier
아래 네트워크는 다음과 같이 정의됩니다.
- 아담 솔버
- ReLU 활성화 함수
- 알파 = 0.0001
- 배치 크기 150개
- 뉴런이 각각 200개와 100개 있는 XNUMX개의 은닉층
model_dnn = make_pipeline(
    preprocess,
    MLPClassifier(solver='adam',
                  alpha=0.0001,
                  activation='relu',
                    batch_size=150,
                    hidden_layer_sizes=(200, 100),
                    random_state=1))
레이어 수를 변경하여 모델의 성능을 향상시킬 수 있습니다.
model_dnn.fit(X_train, y_train)
  print("DNN regression score: %f" % model_dnn.score(X_test, y_test))
DNN 회귀 점수: 0.821253
LIME: 모델을 믿으세요
이제 좋은 모델을 얻었으니, 그 모델을 신뢰할 수 있는 방법이 필요합니다. 머신러닝 알고리즘, 특히 랜덤 포레스트와 신경망은 블랙박스 모델로 알려져 있습니다. 작동은 하지만, 그 이유를 아무도 알 수 없습니다.
세 명의 연구원이 컴퓨터가 예측에 도달하는 과정을 보여주는 도구를 개발했습니다. 그들의 논문은 다음과 같습니다. “내가 왜 당신을 믿어야 하죠?”그들이 발표한 알고리즘은 LIME(Local Interpretable Model-Agnostic Explanations)이라고 합니다.
예를 들어 보겠습니다. 때때로 머신러닝 예측을 신뢰할 수 있는지 확신할 수 없는 경우가 있습니다. 의사는 컴퓨터가 내린 진단이라는 이유만으로 이를 받아들일 수 없으며, 모델을 실제 서비스에 적용하기 전에 신뢰할 수 있는지 여부를 확인해야 합니다.
신경망, 랜덤 포레스트, 임의의 커널을 사용하는 SVM과 같이 복잡한 모델조차도 어떤 이유로 예측을 내렸는지 확인할 수 있다고 상상해 보세요. 예측의 근거가 명확해지면 예측을 신뢰하기가 훨씬 쉬워지고, 반대로 신뢰해서는 안 될 모델을 판단하기도 훨씬 쉬워집니다. LIME은 분류기의 결정에 영향을 미친 특징들을 알려줍니다.
데이터 준비
LIME을 실행하려면 몇 가지 사항을 변경해야 합니다. Python먼저 터미널에서 `pip install lime` 명령어를 사용하여 lime을 설치하세요.
Lime은 LimeTabularExplainer 객체를 사용하여 모델을 국소적으로 근사화합니다. 이 객체를 사용하려면 다음이 필요합니다.
- 데이터 세트 눔 파이 체재
- 기능 이름: feature_names
- 클래스 이름: class_names
- 범주형 기능 열의 인덱스: categorical_features
- 각 범주형 특징에 대한 그룹 이름: categorical_names
NumPy 기차 세트를 생성합니다.
pandas의 df_train을 NumPy로 복사하고 변환하는 것은 매우 쉽습니다.
df_train.head(5)
# Create numpy data
df_lime = df_train
df_lime.head(3)
수업 이름 가져오기
해당 레이블은 unique() 함수를 통해 접근할 수 있습니다. 다음과 같이 표시될 것입니다.
- '<= 50K'
- '> 50'
# Get the class name
class_names = df_lime.label.unique()
class_names
array(['<=50K', '>50K'], dtype=object)
범주형 특징 열에 인덱스를 지정합니다.
이전에 배운 방법을 사용하여 각 그룹의 이름을 가져옵니다. LabelEncoder를 사용하여 레이블을 인코딩하고 모든 범주형 특징에 대해 이 작업을 반복합니다.
##
import sklearn.preprocessing as preprocessing
categorical_names = {}
for feature in CATE_FEATURES:
    le = preprocessing.LabelEncoder()
    le.fit(df_lime[feature])
    df_lime[feature] = le.transform(df_lime[feature])
    categorical_names[feature] = le.classes_
print(categorical_names)
{'workclass': array(['?', 'Federal-gov', 'Local-gov', 'Never-worked', 'Private',
       'Self-emp-inc', 'Self-emp-not-inc', 'State-gov', 'Without-pay'],
      dtype=object), 'education': array(['10th', '11th', '12th', '1st-4th', '5th-6th', '7th-8th', '9th',
       'Assoc-acdm', 'Assoc-voc', 'Bachelors', 'Doctorate', 'HS-grad',
       'Masters', 'Preschool', 'Prof-school', 'Some-college'],
      dtype=object), 'marital': array(['Divorced', 'Married-AF-spouse', 'Married-civ-spouse',
       'Married-spouse-absent', 'Never-married', 'Separated', 'Widowed'],
      dtype=object), 'occupation': array(['?', 'Adm-clerical', 'Armed-Forces', 'Craft-repair',
       'Exec-managerial', 'Farming-fishing', 'Handlers-cleaners',
       'Machine-op-inspct', 'Other-service', 'Priv-house-serv',
       'Prof-specialty', 'Protective-serv', 'Sales', 'Tech-support',
       'Transport-moving'], dtype=object), 'relationship': array(['Husband', 'Not-in-family', 'Other-relative', 'Own-child',
       'Unmarried', 'Wife'], dtype=object), 'race': array(['Amer-Indian-Eskimo', 'Asian-Pac-Islander', 'Black', 'Other',
       'White'], dtype=object), 'sex': array(['Female', 'Male'], dtype=object), 'native_country': array(['?', 'Cambodia', 'Canada', 'China', 'Columbia', 'Cuba',
       'Dominican-Republic', 'Ecuador', 'El-Salvador', 'England',
       'France', 'Germany', 'Greece', 'Guatemala', 'Haiti', 'Honduras',
       'Hong', 'Hungary', 'India', 'Iran', 'Ireland', 'Italy', 'Jamaica',
       'Japan', 'Laos', 'Mexico', 'Nicaragua',
       'Outlying-US(Guam-USVI-etc)', 'Peru', 'Philippines', 'Poland',
       'Portugal', 'Puerto-Rico', 'Scotland', 'South', 'Taiwan',
       'Thailand', 'Trinadad&Tobago', 'United-States', 'Vietnam',
       'Yugoslavia'], dtype=object)}

df_lime.dtypes
age               float64
workclass           int64
fnlwgt            float64
education           int64
education_num     float64
marital             int64
occupation          int64
relationship        int64
race                int64
sex                 int64
capital_gain      float64
capital_loss      float64
hours_week        float64
native_country      int64
label              object
dtype: object
이제 데이터셋이 준비되었으므로 아래 Scikit-learn 예제에 나와 있는 다양한 데이터셋을 구축할 수 있습니다. LIME 관련 오류를 방지하기 위해 여기서는 파이프라인 외부에서 데이터를 변환합니다. LimeTabularExplainer에 전달되는 학습 데이터셋은 문자열이 없는 NumPy 배열이어야 하며, 위의 메서드는 이미 해당 배열을 생성했습니다.
from sklearn.model_selection import train_test_split
X_train_lime, X_test_lime, y_train_lime, y_test_lime = train_test_split(df_lime[features],
                                                    df_lime.label,
                                                    test_size = 0.2,
                                                    random_state=0)
X_train_lime.head(5)
XGBoost가 찾아낸 최적의 매개변수를 사용하여 파이프라인을 구축할 수 있습니다.
model_xgb = make_pipeline(
    preprocess,
    xgboost.XGBClassifier(max_depth = 3,
                          gamma = 0.5,
                          n_estimators=600,
                          objective='binary:logistic',
                          silent=True,
                          nthread=1))

model_xgb.fit(X_train_lime, y_train_lime)
/Users/Thomas/anaconda3/envs/hello-tf/lib/python3.6/site-packages/sklearn/preprocessing/_encoders.py:351: FutureWarning: The handling of integer data will change in version 0.22. Currently, the categories are determined based on the range [0, max(values)], while in the future they will be determined based on the unique values.
If you want the future behavior and silence this warning, you can specify "categories='auto'."In case you used a LabelEncoder before this OneHotEncoder to convert the categories to integers, then you can now use the OneHotEncoder directly.
  warnings.warn(msg, FutureWarning)
Pipeline(memory=None,
     steps=[('columntransformer', ColumnTransformer(n_jobs=1, remainder='drop', transformer_weights=None,
         transformers=[('standardscaler', StandardScaler(copy=True, with_mean=True, with_std=True), [0, 2, 10, 4, 11, 12]), ('onehotencoder', OneHotEncoder(categorical_features=None, categories=None,...
       reg_alpha=0, reg_lambda=1, scale_pos_weight=1, seed=None,
       silent=True, subsample=1))])
경고 메시지가 표시됩니다. 파이프라인 전에 레이블 인코더를 생성할 필요가 없다는 내용입니다. LIME을 사용하지 않는 경우, 이 Scikit-learn을 사용한 머신 러닝 튜토리얼의 첫 번째 부분에 나온 방법을 사용해도 됩니다. 하지만 LIME을 사용하는 경우에는 다음 접근 방식을 유지하세요. 먼저 인코딩된 데이터셋을 생성한 다음, 파이프라인 내에서 원핫 인코더를 적용합니다.
print("best logistic regression from grid search: %f" % model_xgb.score(X_test_lime, y_test_lime))
best logistic regression from grid search: 0.873157
model_xgb.predict_proba(X_test_lime)
array([[7.9646105e-01, 2.0353897e-01],
       [9.5173013e-01, 4.8269872e-02],
       [7.9344827e-01, 2.0655173e-01],
       ...,
       [9.9031430e-01, 9.6856682e-03],
       [6.4581633e-04, 9.9935418e-01],
       [9.7104281e-01, 2.8957171e-02]], dtype=float32)
LIME을 사용하기 전에 잘못 분류된 행의 특징을 저장하는 NumPy 배열을 만드세요. 나중에 이 목록을 사용하여 분류기가 어떤 이유로 오분류되었는지 파악할 수 있습니다.
temp = pd.concat([X_test_lime, y_test_lime], axis= 1)
temp['predicted'] = model_xgb.predict(X_test_lime)
temp['wrong']=  temp['label'] != temp['predicted']
temp = temp.query('wrong==True').drop('wrong', axis=1)
temp= temp.sort_values(by=['label'])
temp.shape
(826, 16)
그다음에는 새 데이터에 대한 모델의 예측값을 가져오는 람다 함수를 생성합니다. 이 함수는 곧 필요하게 될 것입니다.
predict_fn = lambda x: model_xgb.predict_proba(x).astype(float)
X_test_lime.dtypes
age               float64
workclass           int64
fnlwgt            float64
education           int64
education_num     float64
marital             int64
occupation          int64
relationship        int64
race                int64
sex                 int64
capital_gain      float64
capital_loss      float64
hours_week        float64
native_country      int64
dtype: object
predict_fn(X_test_lime)
array([[7.96461046e-01, 2.03538969e-01],
       [9.51730132e-01, 4.82698716e-02],
       [7.93448269e-01, 2.06551731e-01],
       ...,
       [9.90314305e-01, 9.68566816e-03],
       [6.45816326e-04, 9.99354184e-01],
       [9.71042812e-01, 2.89571714e-02]])
pandas 데이터프레임을 NumPy 배열로 변환합니다.
X_train_lime = X_train_lime.values
X_test_lime = X_test_lime.values
X_test_lime
array([[4.00000e+01, 5.00000e+00, 1.93524e+05, ..., 0.00000e+00,
        4.00000e+01, 3.80000e+01],
       [2.70000e+01, 4.00000e+00, 2.16481e+05, ..., 0.00000e+00,
        4.00000e+01, 3.80000e+01],
       [2.50000e+01, 4.00000e+00, 2.56263e+05, ..., 0.00000e+00,
        4.00000e+01, 3.80000e+01],
       ...,
       [2.80000e+01, 6.00000e+00, 2.11032e+05, ..., 0.00000e+00,
        4.00000e+01, 2.50000e+01],
       [4.40000e+01, 4.00000e+00, 1.67005e+05, ..., 0.00000e+00,
        6.00000e+01, 3.80000e+01],
       [5.30000e+01, 4.00000e+00, 2.57940e+05, ..., 0.00000e+00,
        4.00000e+01, 3.80000e+01]])
model_xgb.predict_proba(X_test_lime)
array([[7.9646105e-01, 2.0353897e-01],
       [9.5173013e-01, 4.8269872e-02],
       [7.9344827e-01, 2.0655173e-01],
       ...,
       [9.9031430e-01, 9.6856682e-03],
       [6.4581633e-04, 9.9935418e-01],
       [9.7104281e-01, 2.8957171e-02]], dtype=float32)
print(features,
      class_names,
      categorical_features,
      categorical_names)
['age', 'workclass', 'fnlwgt', 'education', 'education_num', 'marital', 'occupation', 'relationship', 'race', 'sex', 'capital_gain', 'capital_loss', 'hours_week', 'native_country'] ['<=50K' '>50K'] [1, 3, 5, 6, 7, 8, 9, 13] {'workclass': array(['?', 'Federal-gov', 'Local-gov', 'Never-worked', 'Private',
       'Self-emp-inc', 'Self-emp-not-inc', 'State-gov', 'Without-pay'],
      dtype=object), 'education': array(['10th', '11th', '12th', '1st-4th', '5th-6th', '7th-8th', '9th',
       'Assoc-acdm', 'Assoc-voc', 'Bachelors', 'Doctorate', 'HS-grad',
       'Masters', 'Preschool', 'Prof-school', 'Some-college'],
      dtype=object), 'marital': array(['Divorced', 'Married-AF-spouse', 'Married-civ-spouse',
       'Married-spouse-absent', 'Never-married', 'Separated', 'Widowed'],
      dtype=object), 'occupation': array(['?', 'Adm-clerical', 'Armed-Forces', 'Craft-repair',
       'Exec-managerial', 'Farming-fishing', 'Handlers-cleaners',
       'Machine-op-inspct', 'Other-service', 'Priv-house-serv',
       'Prof-specialty', 'Protective-serv', 'Sales', 'Tech-support',
       'Transport-moving'], dtype=object), 'relationship': array(['Husband', 'Not-in-family', 'Other-relative', 'Own-child',
       'Unmarried', 'Wife'], dtype=object), 'race': array(['Amer-Indian-Eskimo', 'Asian-Pac-Islander', 'Black', 'Other',
       'White'], dtype=object), 'sex': array(['Female', 'Male'], dtype=object), 'native_country': array(['?', 'Cambodia', 'Canada', 'China', 'Columbia', 'Cuba',
       'Dominican-Republic', 'Ecuador', 'El-Salvador', 'England',
       'France', 'Germany', 'Greece', 'Guatemala', 'Haiti', 'Honduras',
       'Hong', 'Hungary', 'India', 'Iran', 'Ireland', 'Italy', 'Jamaica',
       'Japan', 'Laos', 'Mexico', 'Nicaragua',
       'Outlying-US(Guam-USVI-etc)', 'Peru', 'Philippines', 'Poland',
       'Portugal', 'Puerto-Rico', 'Scotland', 'South', 'Taiwan',
       'Thailand', 'Trinadad&Tobago', 'United-States', 'Vietnam',
       'Yugoslavia'], dtype=object)}
import lime
import lime.lime_tabular
### Train should be label encoded not one hot encoded
explainer = lime.lime_tabular.LimeTabularExplainer(X_train_lime ,
                                                   feature_names = features,
                                                   class_names=class_names,
                                                   categorical_features=categorical_features,
                                                   categorical_names=categorical_names,
                                                   kernel_width=3)
이제 테스트 세트에서 무작위로 가구를 하나 선택하고 예측 결과와 컴퓨터가 그 결과에 도달한 과정을 모두 확인해 보세요.
import numpy as np
np.random.seed(1)
i = 100
print(y_test_lime.iloc[i])
>50K
X_test_lime[i]
array([4.20000e+01, 4.00000e+00, 1.76286e+05, 7.00000e+00, 1.20000e+01,
       2.00000e+00, 4.00000e+00, 0.00000e+00, 4.00000e+00, 1.00000e+00,
       0.00000e+00, 0.00000e+00, 4.00000e+01, 3.80000e+01])
explain_instance를 사용하여 설명자를 실행하면 모델의 근거를 살펴볼 수 있습니다. 표시되는 차트는 아래와 같습니다.
exp = explainer.explain_instance(X_test_lime[i], predict_fn, num_features=6)
exp.show_in_notebook(show_all=False)

분류기가 이 가구를 정확하게 예측했습니다. 소득은 실제로 50만 달러 이상입니다.
우선, 분류기가 아직 확신하지 못한다는 점을 알아두어야 합니다. 50만 달러 이상의 소득을 예측할 확률은 64%이며, 이 64%는 자본 이득과 결혼 여부에 의해 좌우됩니다. 파란색 선은 긍정 범주에 부정적으로 기여하고, 주황색 선은 긍정적으로 기여합니다.
분류기는 이 가구의 자본 이득이 0이기 때문에 확신하지 못합니다. 일반적으로 자본 이득은 부를 예측하는 좋은 지표이기 때문입니다. 또한 이 가구는 주당 40시간 미만으로 일합니다. 연령, 직업 및 성별은 모두 긍정적인 영향을 미칩니다.
혼인 상태가 미혼이었다면 분류기는 소득이 50만 달러 미만일 것으로 예측했을 것입니다(0.64 – 0.18 = 0.46).
이제 잘못 분류된 다른 가구를 시도해 보세요. 해당 가구에 대한 설명표는 코드 다음에 나옵니다.
temp.head(3)
temp.iloc[1,:-2]
age                  58
workclass             4
fnlwgt            68624
education            11
education_num         9
marital               2
occupation            4
relationship          0
race                  4
sex                   1
capital_gain          0
capital_loss          0
hours_week           45
native_country       38
Name: 20931, dtype: object
i = 1
print('This observation is', temp.iloc[i,-2:])
This observation is label        <=50K
predicted     >50K
Name: 20931, dtype: object
exp = explainer.explain_instance(temp.iloc[1,:-2], predict_fn, num_features=6)
exp.show_in_notebook(show_all=False)

분류기는 소득을 50만 달러 미만으로 예측했는데, 이는 잘못된 예측입니다. 이 가구는 특이한 특징을 가지고 있습니다. 자본 이득이나 손실이 없고, 가장은 이혼했으며, 나이는 60세에 가깝고, 교육 수준도 높습니다(education_num > 12). 이러한 전반적인 패턴을 따라 분류기는 해당 가구의 소득을 50만 달러 미만으로 분류했습니다.
LIME을 직접 사용해 보시면 분류기의 수많은 명백한 오류를 발견하게 될 것입니다. 라이브러리 개발자의 GitHub 저장소에는 이미지 및 텍스트 분류에 대한 추가 문서가 있습니다.
Scikit-learn 명령어 참조
다음은 scikit-learn 버전 0.20 이상에서 사용할 수 있는 유용한 명령어 목록입니다.
| 태스크 | 함수 또는 클래스 |
|---|---|
| 학습/테스트 데이터셋을 생성합니다. | train_test_split |
| 파이프라인 구축 | |
| 열을 선택하고 변환을 적용하세요. | 컬럼 트랜스포머 만들기 |
| 변환 유형 | |
| 표준화하다 | 표준 스케일러 |
| 최소-최대 스케일링 | 최소 최대 스케일러 |
| 정상화하다 | 노멀 라이저 |
| 결측값 대체 | 단순 점프 |
| 범주형으로 변환 | 원핫인코더 |
| 데이터 맞춤 및 변환 | 적합_변형 |
| 파이프라인을 만드세요 | make_pipeline |
| 기본 모델 | |
| 로지스틱 회귀 | 로지스틱 회귀 |
| XGBoost | XGB분류기 |
| 신경망 | MLP분류자 |
| 그리드 검색 | 그리드서치CV |
| 무작위 검색 | 무작위 검색CV |
